






Every partner, a different format
KeHE, Costco, Dot Foods and dozens more each send their own layout. A parser tuned for one breaks on the next.
Plug-and-play deduction AI for CPG finance teams
Generic document AI has to be trained on your formats for weeks before it is any use. intelliExtract already understands CPG remittances, billbacks and scanned backup packets — so you send a document and get the deduction fields and UPC lines back as clean JSON in seconds.
Plug-and-play · No templates, no training · Free first extraction, no credit card
Generic document AI
intelliExtract
Weeks of training per format
Works on your first packet
A template for every retailer
Knows KeHE, Costco and Dot Foods already
A separate OCR step for scans
Scans and PDFs through one endpoint
Generic document AI
intelliExtract
Pattern-aware across major CPG retailers and distributors
Live preview
Sample CPG fixtures, anonymised and static, grounded in real remittance and backup workflows. Pick a document to compare the source against what the API returns.
Sample document
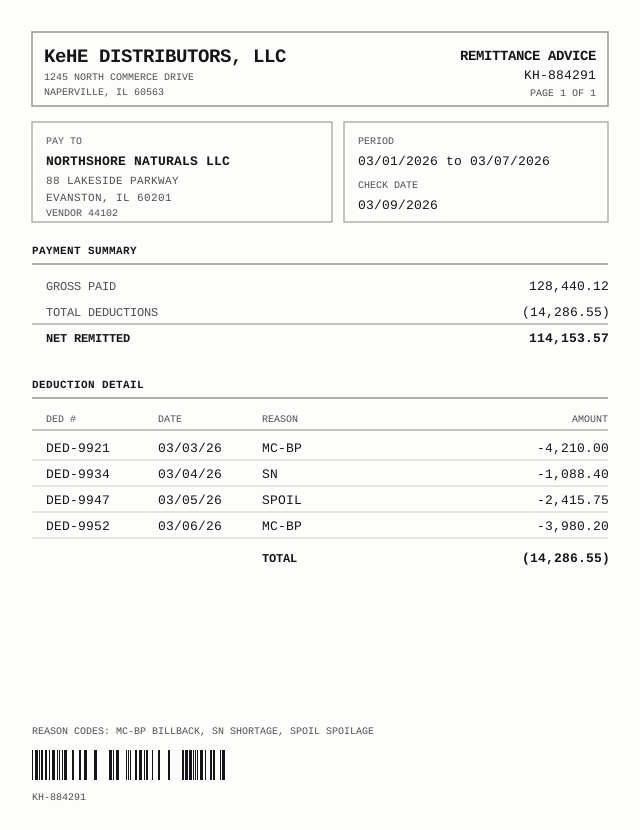
KeHEPayment advice with deduction summary across DCs — typical weekly remittance packet.
Text layer read
REMITTANCE ADVICE
Purchaser: KeHE Distributors
Vendor: Northshore Naturals LLC
Check / Payment Ref: KH-884291
Period: 03/01/2026 – 03/07/2026
Gross Paid: $128,440.12
Total Deductions: ($14,286.55)
Net Remitted: $114,153.57

Ded #  DED-9921  Reason MC-BP  -$4,210.00
Ded #  DED-9934  Reason SN     -$1,088.40
Extracted header
Line items
| UPC | Item | Unit | Allow. | Total |
|---|---|---|---|---|
| 00850123456789 | Organic Almond Butter 12oz SKU 44102 | $6.40 | $0.35 | $210.00 |
| 00850123456802 | Seed Crackers Sea Salt 5oz SKU 44118 | $3.15 | $0.12 | $88.40 |
| 00850123456826 | Cold Brew Concentrate 32oz SKU 44201 | $8.90 | $0.50 | $445.00 |
| Line item subtotal | $743.40 | |||
The CPG deduction problem
Remittance advice, multi-page backup PDFs, billbacks and scanned POD or BOL evidence arrive from every trading partner you serve. intelliExtract recognises the purchaser and document type, pulls the fields your team needs, and hands structured results to the systems you already run.
KeHE, Costco, Dot Foods and dozens more each send their own layout. A parser tuned for one breaks on the next.
Backup packets mix native PDFs with photographed BOL and POD pages, so plain text extraction quietly misses lines.
Disputes, posting and cash recovery all wait on someone retyping deduction numbers into a spreadsheet.
Why teams switch
The same extraction that powers the demo above, working on your real packets.
Validate and dispute deductions from structured fields and reason codes, not from numbers retyped into a spreadsheet.
Classifies purchaser and document type first, then extracts line items from scans and native PDFs in the same packet.
Clean JSON delivered by webhook or synchronously, so there is no new interface for your team to learn.
Document types
Focused on trade deductions, not generic “any PDF” OCR.
Payment detail and deduction summaries: check references, periods, reason codes and net remitted amounts.
Fields extracted
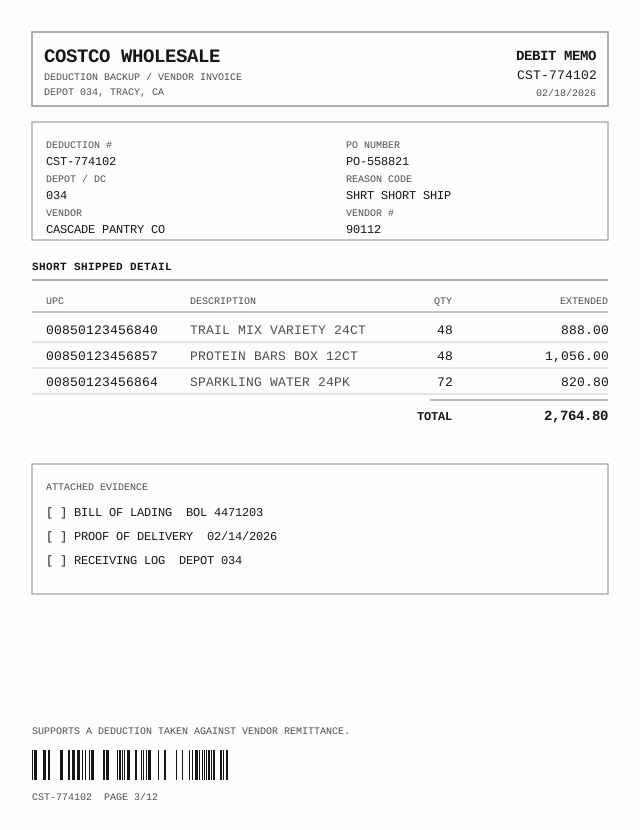
Supporting deduction docs: vendor invoices, BOL and POD evidence, billbacks and debit memos in one packet.
Fields extracted
How it works
Features
Purchaser, document type and billback tags are recognised first, so each field set matches the packet in hand and the right prompt runs every time.
Text, scanned and mixed pages handled through one endpoint — no separate OCR job to run first.
Long backup packets are read end to end, with line items assembled across pages into one result.
Remittance spreadsheets and images are accepted alongside PDFs, or fetched straight from a URL.
A never-seen layout is flagged and captured for review instead of silently dropping fields.
HMAC-authenticated classify and extract endpoints: clean JSON by webhook or synchronous response, built to drop into the systems you run.
See it on your own packet
Free first extraction, no credit card. Enter your work email and we email the structured result back to you.
Prefer a walkthrough? Book a demo →
Answers before you ask
What a CPG deduction is, what the API handles today, and what happens when a packet does not look like the last one.
A CPG deduction is money a retailer or distributor subtracts from a payment to a brand — for promotional allowances, shortages, pricing errors or compliance chargebacks. To recover the cash, the brand has to match each deduction to its backup document, confirm whether it is valid, and dispute the rest. intelliExtract turns those documents into structured data so that matching is automatic.
No. intelliExtract already understands CPG deduction documents, so there are no templates to build and no model to train before it works. Generic document AI has to be taught each retailer layout first; here the classification and extraction patterns for remittances, backup packets and billbacks ship with the product.
Remittance advice and deduction backup packets: vendor invoices, BOL and POD evidence, billbacks and debit memos. It is built for CPG trade deductions rather than generic “any PDF” OCR, so each document type has its own field set and its own extraction prompt.
Both, through the same endpoint. Text-based, scanned and mixed packets are handled without a separate OCR workflow to run first. Images and remittance spreadsheets are accepted too, and a document can be fetched from a URL instead of uploaded.
Upload the packet as a PDF, scan or spreadsheet, or point the API at its URL. intelliExtract classifies the purchaser and document type first, then extracts the header fields and line items — UPCs, SKUs, reason codes, allowances and totals — and returns them as clean JSON by webhook or in the response.
Classification and extraction patterns cover major CPG retailers and distributors, including KeHE, Costco, Dot Foods, UNFI, Kroger, H-E-B, Walmart, Target, Amazon, SuperValu, C&S, Meijer, BJ’s, Sobey’s and Davidson.
The document is captured and routed for ops follow-up instead of failing silently, so an untrained layout surfaces as a task your team can act on rather than disappearing from the queue or coming back with quietly mis-mapped fields.
Yes. Long backups are chunked and extracted across pages, then headers are aggregated and line items appended, so a twelve-page packet comes back as one structured result rather than twelve fragments.
Through HMAC-authenticated classify and extract endpoints. Structured JSON is delivered by webhook, or returned synchronously in the response, whichever suits the workflow you are wiring it into.
Verify your work email and upload one document: we run the extraction and email the structured result back, one per email address. For volume, a guided rollout or questions about the API, book a demo.
Send one packet and watch it come back as clean, structured JSON — or book a call and we will run it on yours.